Semantic Type Annotation in Exported Schemas
Labeling what columns actually mean unlocks schema matching, data cleaning, and discovery.
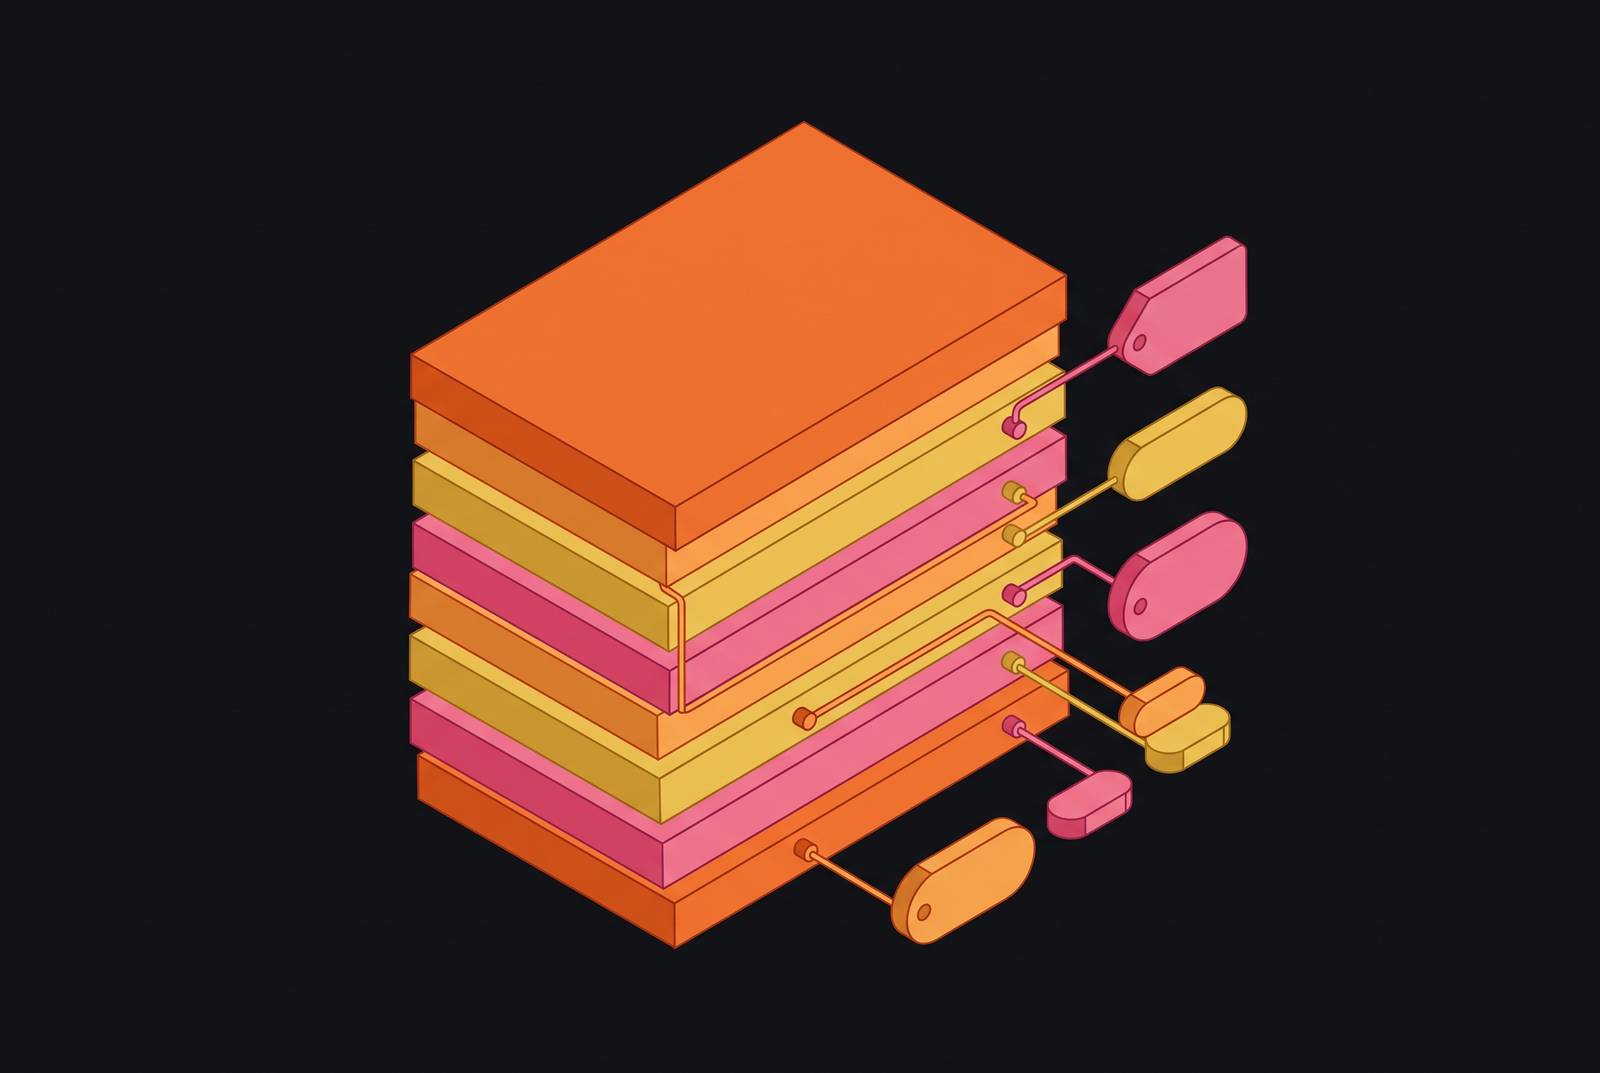
A column named amt_ttl_pre_dsc can pass every structural check a schema export tool runs and still tell a downstream consumer nothing useful. The field is numeric, nullable or not, properly typed. None of that says whether the number is gross revenue, net revenue, or a discount basis applied before some other calculation. That gap sits at the center of what semantic type annotation exists to fix, and it is the subject of this piece. Schema export, as most systems perform it today, captures field names, data types, and nullability. It does not capture what a column means in the real world, and a type-checker has no way to notice the absence.
You can draw a distinction here between atomic types and semantic types. An atomic type like Integer or Boolean describes how a value is stored. A semantic type like BirthPlace or Country names what the value stands for in the real world. RECA's authors treat this distinction as foundational to any downstream use of tabular data, and the reasoning holds up: two columns can share an atomic type and mean entirely different things, and a system that only tracks atomic types has no mechanism for telling them apart.
Research on column-to-concept mapping lists the downstream tasks that depend on getting this right: schema matching, data cleaning, dataset discovery, and feature engineering in machine learning. All four need to know what a column means, not just how it's stored, and structural metadata alone can't support any of them reliably. A schema matcher trying to align a revenue column across two systems has no way to confirm the match is correct if both columns are typed as plain numerics with no semantic label attached.
The problem gets worse in schemaless environments. The Schema Validation and Evaluation Framework paper notes that document-oriented databases let structure vary from record to record and evolve without versioning, so automated schema extraction is needed to recover logical structure. An extracted schema, though, is only as good as its semantic accuracy. Recovering the shape of the data solves only half the problem, since annotation is what tells a consumer what each recovered field actually represents.
What semantic type annotation does to a schema
Semantic type annotation names the real-world concepts behind a column's data, so you can read what it means without digging up documentation or guessing from how the column was named. The canonical example from IBM Research and UMass Amherst's C² paper makes the mechanism concrete: a column containing values like "USA," "UK," and "China" carries the semantic type Country. That label is the annotation. It's a small piece of information that lets a schema matcher align the column with its counterpart in another system, lets a validation engine generate the right rule set for it, and lets a visualization tool choose the right chart type for it automatically.
Annotation works at the column level, and it produces a label drawn from a concept space. That concept space can come from a knowledge graph such as DBPedia or Wikidata, from an open data lake of tables, or from a domain-specific ontology an organization defines for itself. The source of the concept space varies by implementation, but the operation is the same: look at the contents of a column and assign it a label that names what it represents, not just how it's formatted.
Trigyan's data management patent treats semantic type detection and machine-learning-based profiling as a defined step inside the data model and asset definition phase of a pipeline. Annotation is infrastructure that precedes integration, built before data moves rather than patched on after something breaks, so a schema carries meaning from the moment it is created instead of acquiring it after a downstream failure forces the fix. Annotation does more than attach a single label to a column, too. It enriches a schema along several dimensions at once: data quality rules, mapping rules, entity relationships, and temporal evolution. The Schema Validation and Evaluation Framework gives these dimensions formal names: Data Type Accuracy, Required and Optional Fields, Multiple Type Support, Collection Structure Consistency, Entity Relationships, and Temporal Evolution Detection. A well-annotated schema carries information across all six, not just a type label sitting next to a column name.
Why annotation is harder than it looks at schema export time
You often can't tell a semantic type from column content alone, and every method built to resolve that ambiguity fails in its own particular way depending on the data it meets. RECA's authors illustrate the ambiguity with a clean case: the first columns in three separate tables all contain names of artworks. Two of those columns carry the correct semantic label TelevisionShow. The third carries VideoGame. The column content looks identical across all three. The correct annotation is not, and no amount of staring at the values in isolation settles which label belongs where.
Most commercial systems still lean on rule-based and regex matching to identify column types, and the C² paper documents this approach as brittle. Predefined patterns catch what they were built to catch and nothing else; they aren't resistant to noisy data, and they don't generalize past the patterns someone wrote in advance. Supervised learning approaches run into a different wall: training a deep learning classifier to recognize a semantic type takes a large amount of gold-standard labeled data, and that data is scarce for anything outside the most common types. Real-world tables carry a long tail of semantic types, so full coverage costs a lot to reach no matter how good the model architecture is.
Language-model-based methods carry their own ceiling. TABBIE and DODUO, both cited in the RECA paper, use BERT as their core model, and BERT enforces a hard limit on input length. That limit keeps these methods from handling wide tables effectively, and wide tables are not an edge case in production environments. Tables with hundreds of columns are common in operational data systems, and a method that can't take in the full width of a table is working with partial information by construction.
Cross-table context gets ignored just as often, but the effect on annotation quality is a separate problem from the wide-table one. A column annotated by itself loses access to the topic and schema of the tables around it, and that surrounding context often carries the exact signal needed to resolve an ambiguous case, the artwork example being a direct illustration. RECA identifies this as its own distinct failure mode, not a variant of the wide-table limitation.
Numerical columns remain a persistent weak spot across the field. Knowledge-graph-based methods such as Colnet and HNN were built primarily for textual, categorical columns, and they don't generalize to numerical types like population or area. The C² paper identifies this gap directly and notes that prior work leaves it unaddressed. Research from the Schema Validation and Evaluation Framework backs up the broader pattern: existing schema extraction methods score well on basic type reconstruction, but real differences remain in how they handle conditional fields, complex collection structures, and schema evolution over time. Those harder dimensions are exactly the ones integration accuracy depends on most. None of this argues against pursuing annotation. It argues for building methods that can survive contact with the conditions production data actually creates.
Annotation Methods for Wide Tables and Cross-Table Context
The annotation approaches that hold up best combine intra-table and inter-table context from the start, and they're built from the ground up to handle wide tables without truncating input or resorting to ad-hoc workarounds. RECA tackles both failure modes at once: it finds and aligns schema-similar, topic-relevant tables using a named entity schema, folds that related-table context into each column's representation, and by design sidesteps the input-length ceiling that trips up BERT-based methods on wide tables. The architecture treats related tables as a source of signal.
The C² approach takes a different route to a related end. It applies maximum likelihood estimation through ensembles and draws on both open table corpora and curated knowledge graphs at the same time. Pulling from both sources addresses the data-scarcity problem that limits rare semantic types, and it also handles cell values that don't appear in any single knowledge graph on their own, since a value missing from one source might still appear in the open corpus or a different graph.
Overlapping concepts present a separate design challenge, and the strongest methods treat it as one. A person who plays professional sports fits both the Person and SportsPerson concepts, and a classifier forced to pick one label loses information the other label would have carried. When ensemble approaches model that overlap explicitly instead of treating concept boundaries as hard binary lines, they outperform single-label classifiers on exactly this kind of case. The pattern across both RECA and C² points to a shared principle: good annotation architecture treats context, whether from related tables or from overlapping concept definitions, as something to model directly rather than something to discard for the sake of a simpler pipeline.
Placement of Semantic Annotations in a Data Export Stack
Knowing how to annotate well still leaves open the question of where the annotation should be stored and governed once it exists, and the field has no settled answer. The right placement depends on what the exported schema has to serve on the other end, and each of the available positions trades one strength for one real cost.
The warehouse-native position stores annotations as first-class schema objects inside the data warehouse itself, an approach Snowflake's semantic views illustrate. Keeping annotation close to the data this way makes it available to any tool that queries the warehouse directly. It also creates a lock-in risk once an exported schema has to serve multi-cloud or hybrid environments, because far fewer tools can push annotation changes back into the warehouse than can simply read them out.
A dedicated semantic layer takes a different approach: it sits in front of several data sources at once and holds approved formulas, valid joins, and concept definitions independent of any single warehouse. That independence makes annotations portable across sources. It also introduces a synchronization dependency: when the underlying data changes, something has to keep the semantic layer's definitions in step with it, and that upkeep doesn't happen automatically.
The pipeline-embedded position, visible in Trigyan's patent architecture and in QlikTech's reusable semantic types patent, defines annotations once as reusable objects inside the integration engine and applies them consistently across every export the engine produces. This makes annotations portable across every export, but it requires the integration platform itself to act as the single authoritative source of semantic truth, a requirement not every organization's tooling can meet.
The model-YAML position, illustrated by dbt's approach, embeds semantic annotations directly inside data model definition files, keeping annotation in version control alongside the transformations that produce the data. That proximity to the transformation logic is useful for teams who already live in that workflow. It also couples annotation governance to that workflow, and not every team that consumes the data controls it.
None of these four positions escapes a shared vulnerability. Any placement that isn't the single source of truth creates a synchronization problem somewhere else in the stack. Warehouse-native annotations drift from whatever the BI layer has defined on its own. Pipeline-embedded annotations drift from what's actually sitting in the warehouse. YAML-embedded annotations fall out of step as soon as a data structure changes without a matching update to the model file. The choice of where annotation lives is a matter of deciding which synchronization problem an organization is willing to manage on an ongoing basis.
Portability across environments and consumers for an annotated schema
An architectural placement that works inside one environment can still fail the moment the schema leaves it, and that failure mode is separate from the placement debate above. Semantic annotations lose their value in direct proportion to how much they depend on context that doesn't travel with the data. An annotation that only makes sense inside the warehouse where it was defined is useless to the downstream consumer who receives the exported schema somewhere else.
The Schema Validation and Evaluation Framework treats this as a formal schema quality problem, not a convenience issue. An exported schema that fails to capture temporal evolution, conditional fields, and complex collection structures accurately cannot be used reliably for data integration or query optimization by a consumer who wasn't present when the schema was originally defined. The consumer has no way to reconstruct missing context after the fact.
BI tools make the stakes concrete. The C² paper documents that commercial systems including Google Data Studio, Microsoft Power BI, Tableau, and Trifacta all use semantic annotations to understand incoming data, flag discrepancies, and generate visualizations automatically. An annotation that doesn't survive export intact doesn't just create an inconvenience for an analyst. It produces a wrong visualization, built on a label the tool trusted and the data no longer supported.
AI agents add a runtime requirement on top of that. An agent querying exported data at the point of use needs machine-consumable semantic annotations to constrain what it does with that data. A system that produces annotation in a human-readable form but nothing a machine can parse structurally fails the moment an agentic workflow tries to use it, regardless of how accurate the underlying labels are.
Private-cloud and air-gapped deployments push the portability requirement to its hardest form. Annotations have to travel with the schema into environments where the service or knowledge graph that originally generated them isn't reachable. That constraint rules out any annotation architecture that depends on a live connection back to a semantic layer to resolve labels at query time. The annotation has to be complete and self-contained at the moment of export, because there won't be a second chance to look anything up.
How governance failures in annotation break downstream trust
When semantic annotations are wrong or missing, the damage doesn't stop at a dashboard rendering the wrong chart. It becomes a governance failure, because consumers end up making decisions on data they have no way to confirm they've understood correctly. Schema matching is the primary mechanism integration systems use to align data from different sources, and both the C² paper and RECA treat accurate semantic type identification as the foundational input that matching depends on. A misannotated column that gets matched to the wrong target field in an integration pipeline doesn't throw an error. It produces integrated data that is silently incorrect, and silent incorrectness is far more expensive to catch than a visible failure.
Trigyan's patent architecture makes the same point from the data quality side. Its data quality engine service works directly on the annotated knowledge graph, and its data quality rules are defined in terms of semantic types, not raw column names or atomic types. Those quality rules depend on reliable annotation underneath them; without it, they can't be applied correctly, and any quality score the system produces stops meaning anything. The score keeps appearing on a dashboard somewhere, confident and specific, resting on a label that was never accurate to begin with.
Sources
- Methods and systems for data management, integration, and interoperability
- Semantic Annotation for Tabular Data
- RECA: Related Tables Enhanced Column Semantic Type Annotation Framework
- Schema validation and evaluation framework for extracted schemas in JSON databases
- Method and system for developing data integration applications with reusable semantic types to represent and process application data