Foreign Key Declaration in Exported Schemas Without Enforcement
Cloud warehouses declare foreign keys for optimizer hints, not enforcement.
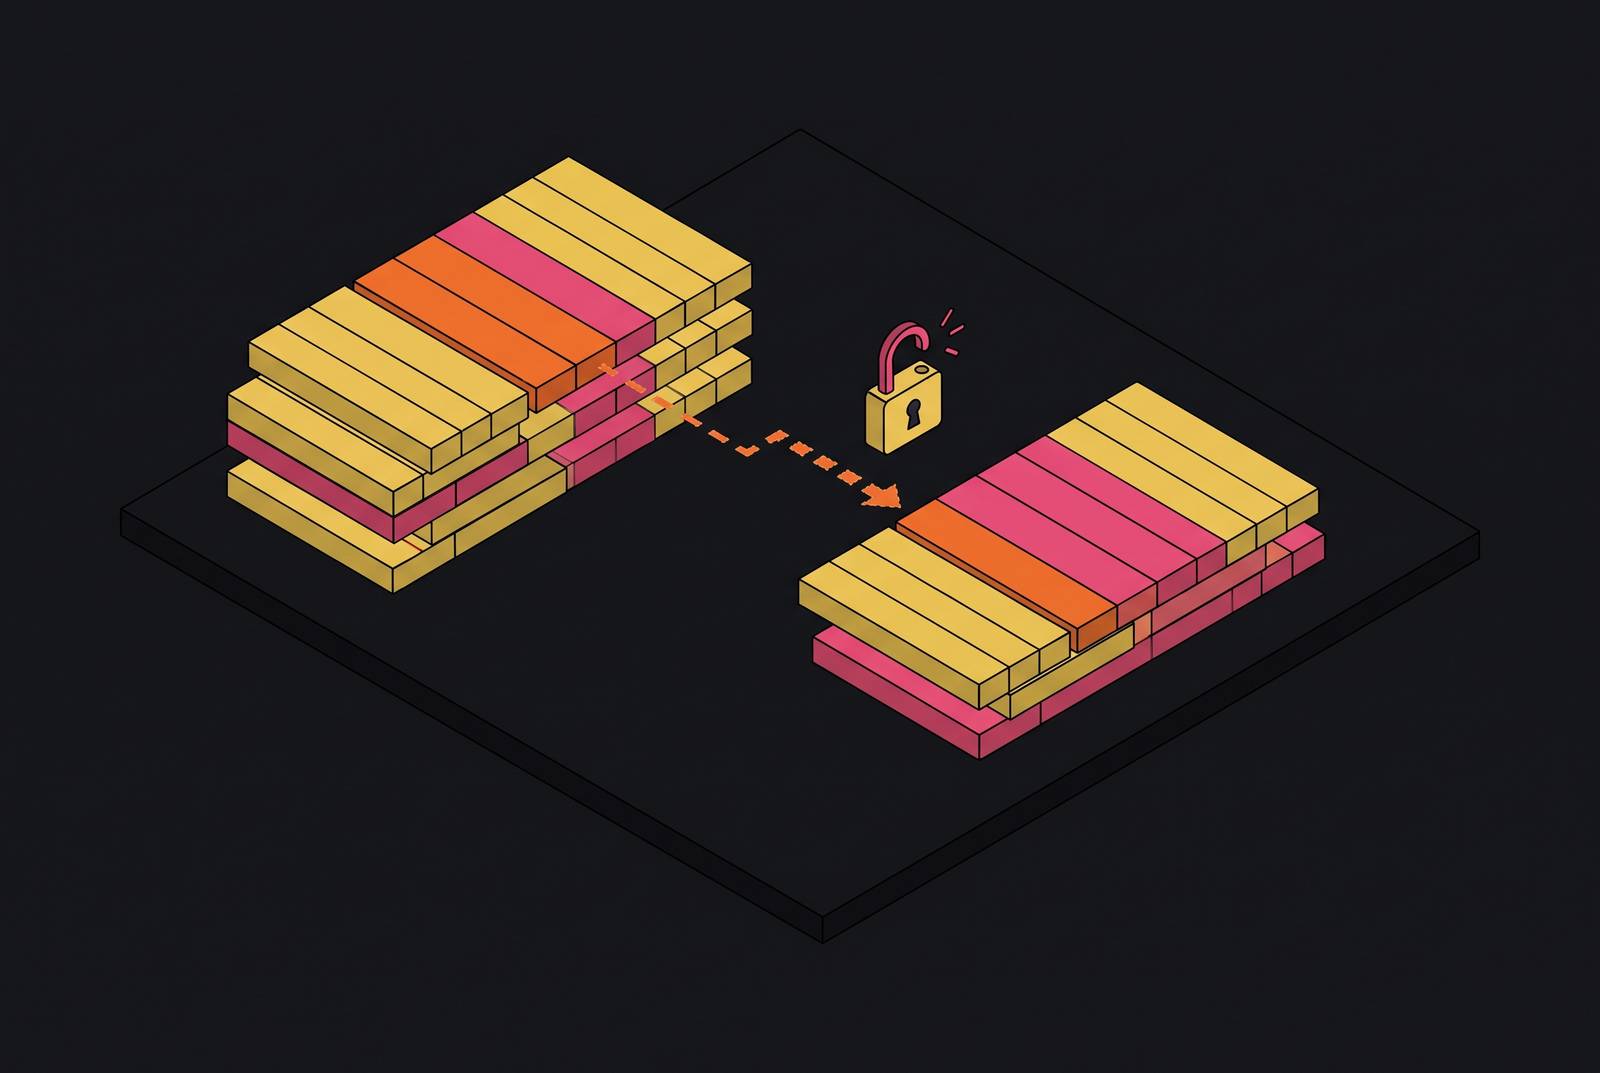
A foreign key, when a database actually enforces it, works as a gate at the moment of the write. Two tables sit on either side of that gate: a parent table holding the referenced value, usually its primary key, and a child table holding the column that points back at it. The engine checks every insert, update, and delete against that relationship, and it does not matter who or what is doing the writing. An application that forgets to validate a foreign key, a script that skips a business rule, a developer typing a fix straight into a console session: all of it hits the same wall, because the constraint lives in the engine, not in whatever code happened to generate the write. That is the whole distinction between a declared constraint and the same logic scattered across application code. Enforcement also decides what happens next when a parent row disappears or changes: CASCADE, SET NULL, SET DEFAULT, RESTRICT, and NO ACTION each produce one deterministic outcome at the row level, atomically, in a way that a check bolted onto the application layer cannot promise. That reliability is the entire point, and it is what gets set aside in the systems the rest of this piece is about.
Why every major cloud warehouse accepts the declaration and skips the enforcement
That is not a gap somebody forgot to close. It is a documented, deliberate stance built into how each platform works, and the reasoning behind it comes down to what these systems are actually for.
Warehouses load data in batches, often huge ones, a row-by-row trickle of a transactional system. Checking every foreign key on every row of every batch adds write-time cost that buys nothing back, since the whole architecture is optimized around getting large volumes of data in fast. The workload on the read side tells the same story from the other direction: warehouse query planning is built for large, read-heavy joins across star schemas, and none of that benefits from a constraint check that only slows down the write. The Kimball Forum's long-standing position was that ETL, being a controlled and auditable process on its own, should carry the burden of referential integrity instead of the database, with RI validation folded into a larger pipeline rather than pushed onto the engine. A newer framework from datawarehouseinfo.com, dated May 2026, updates that view: it argues for informational constraints in the DDL paired with checks run in the transformation layer, rather than leaning on ETL alone to catch every violation.
Each platform's documentation of this shows the pattern repeating with only minor variation. Snowflake treats foreign key constraints as informational only on standard tables; NOT NULL gets enforced, CHECK gets enforced for DML (though not for COPY INTO), and referential integrity sits outside all of that. BigQuery added foreign key and primary key support in 2023, unenforced at write time but read by the optimizer for join planning. Redshift treats foreign keys as informational by default, and its RELY clause tells the optimizer to trust a declared constraint for query rewrite without ever validating it. Databricks does the same on Unity Catalog tables, with RELY available there too. Lakehouse table formats, Iceberg and Delta among them, carry this same split down to the format layer: constraints can live in catalog metadata, but whether anything enforces them depends entirely on which query engine is doing the reading.
Microsoft Fabric states the intent more directly than any of the others. A foreign key on Fabric can only be declared with NOT ENFORCED attached, and that keyword is not optional syntax you can flip on later; it is required. Where Snowflake and BigQuery's documentation reads as a quiet acknowledgment that enforcement is skipped, Fabric's syntax makes the same decision structural. You cannot even write the constraint without also writing the admission that nothing will check it.
What the declaration is still doing (optimizer hints, join planning, and BI tool auto-configuration)
None of this makes the declaration pointless. All three depend on one condition, that the metadata is accurate and actually present, which is the thread the rest of this piece pulls on.
Start with the optimizer. Redshift and Databricks both use the RELY clause to let the query planner trust a declared foreign key enough to skip scanning a dimension table it does not need to touch. SQL Server takes a related but distinct approach in its star-query optimizations: it uses pattern matching, based on table size and join shape, to enable bitmap filtering between fact and dimension tables, and the join predicate does not even need to be a strict primary-key-to-foreign-key match, just a declared single-column join. Oracle's Tom Kyte, in the Ask TOM guidance cited by datawarehouseinfo.com, goes further and calls constraints, foreign key metadata included, vital to good performance, on the grounds that the optimizer is working blind without them.
BI tools lean on the same metadata for a more mundane but no less useful reason: most of them read FK definitions off the tables during import and build the join conditions automatically, which saves time and avoids the errors that creep in when someone configures joins by hand. Some tools push further and use the constraint for query rewrite, including join elimination, which is a real performance win at the BI layer even though the warehouse engine never checked whether the constraint actually holds.
There is a documentation benefit sitting underneath all of this too. A declared foreign key encodes the intended relational model inside the schema itself, rather than in a separate wiki page or data dictionary that can drift out of sync. That matters even more once you consider who else is reading the schema. AI agents that need to figure out how tables relate to each other depend on exactly this kind of declared metadata as the connective tissue of the join graph, and without it they are left inferring relationships or having them hardcoded by hand, a problem to return to later. Every one of these benefits, the optimizer hint, the BI auto-join, the lineage, the agent's join path, rests on the same assumption: that the declaration is both correct and visible to whatever is trying to read it. That assumption breaks more often than it should. DbSchema's diagram view draws each FK as a line between tables, a visual signal that makes missing constraints immediately visible during schema review.
Where the metadata breaks down (the JDBC gap in Microsoft Fabric and the virtual FK workaround)
Declaring a foreign key in the warehouse does not guarantee that anything downstream can see it. Microsoft Fabric is the clearest documented case of metadata that exists inside the engine and simply fails to travel through standard tooling.
The mechanism, according to the Microsoft Fabric Community documentation, is specific. A call to getImportedKeys() or getExportedKeys(), the standard JDBC calls a tool uses to ask "what does this table connect to," can come back empty against Fabric Warehouse and Lakehouse endpoints, because relationship metadata is not exposed through those calls at all. This is not a bug that will get patched next release. It is a documented consequence of foreign keys being informational rather than enforced, and that informational status means the constraints are not consistently surfaced through JDBC's imported and exported key metadata. The practical result lands on any tool or SDK that discovers join relationships by calling JDBC metadata APIs: it will silently fail to find foreign keys on Fabric even when those relationships were explicitly declared. Nothing throws an error. The relationship is simply absent from what the tool sees, which is a worse failure mode than an error, because nobody gets told to go looking for the problem.
DbSchema's answer to this is a pattern called the virtual foreign key. It is stored in the model file, never written to the database, so it creates no constraint inside the engine at all, but it appears everywhere the tool treats relationships as real, the diagram, the Query Builder, the Relational Data Editor. Declaring the relationship in a model layer instead of the engine itself is becoming the standard move for embedded SDK query builders that cannot count on the warehouse's JDBC layer to hand back consistent relationship data. The implication for anyone building on Fabric, or on a platform with similar gaps, is that the model layer, whether that is an SDK, a semantic layer, or a data catalog, has to carry foreign key metadata on its own terms, independent of whatever the underlying engine is willing to expose over JDBC.
How schema drift turns silent non-enforcement into a live data quality failure
None of this stays theoretical for long, because source systems change constantly, and a warehouse that never checks a foreign key at write time will not tell anyone when a change has quietly broken one. A renamed identifier in the source system, a column narrowed from bigint to integer, a record deleted out of the CRM: any of these can sever an implied foreign key relationship without the warehouse rejecting a single row on the way in. The load succeeds. The dashboard looks fine, right up until someone runs the one query that depends on the join that no longer resolves.
Not every schema change carries the same weight, and treating them as if they do is a mistake. A new nullable column is a low-stakes addition; a renamed identifier is a different kind of problem entirely, and a type narrowing is different again, closer to a contract violation than a cosmetic edit. The datawarehouseinfo.com framework from May 2026 frames this explicitly as a contract decision, not a maintenance footnote.
SaaS data sync makes the same failure mode concrete. Relational integrity there means parent records land before their children, and that relationships like Accounts to Contacts, or Opportunities to Opportunity Line Items, survive the trip into the destination warehouse intact. If load ordering slips, if a batch of contact records arrives before the accounts they belong to, the warehouse accepts the orphaned children without complaint, because nothing in the engine is watching for that. The dataset can be technically complete, every row loaded, every batch acknowledged, and still be relationally broken in exactly the way that ruins the join queries the whole sync existed to support.
There is a compliance angle worth a single mention here. Schema metadata handed over as part of a data contract implies a relational guarantee that the engine is not actually backing up, and that gap matters for any team operating under SOC 2, GDPR, or HIPAA, where schema and provenance validation are documented as controls. SOC 2 in particular expects validated schema and provenance, immutable logging, and active monitoring for anomalies, and an unenforced foreign key that silently swallows an orphaned row works against all three at once. Relational integrity during SaaS data sync.
Where the integrity check should live (transformation-layer assertions as the modern default)
None of this argues for restoring engine-level enforcement across the board. It argues for moving the check to where it can actually run without slowing anything down: the transformation layer, after the load completes, where a violation gets flagged and routed aside instead of halting the whole pipeline.
The decision here is not a binary choice between enforcement and nothing, per datawarehouseinfo.com's decision framework. The first, engine-enforced foreign keys, only exists in practice on traditional RDBMS warehouses, SQL Server, Oracle, DB2, PostgreSQL-based systems, and Teradata running on-prem, plus a handful of cloud engines where it takes explicit configuration; it is simply not on the table for Snowflake standard tables, BigQuery, Redshift, or Databricks. The second option is the one that actually fits how these platforms work: declare foreign keys in the DDL for the optimizer hints and the lineage benefit, and run post-load tests, dbt's relationships tests, SQLMesh audits, Great Expectations expectations, to catch the violations that actually occur. That combination is the modern default for a cloud warehouse stack. The third option, unenforced with no assertions running anywhere, is almost always the wrong answer, and it is the old "we'll catch it in ETL" position that, in practice, tends never to quite catch it.
When a transformation-layer test does catch a violation, failing the whole load over it is the wrong response. The better pattern routes the offending row into a quarantine table, tagged with an unknown-member surrogate key, so the morning's reporting run keeps moving while the violation stays visible and auditable rather than buried. Halting an entire pipeline because one late-arriving record has no matching parent yet is a worse outcome than quarantining it and fixing it on the next pass.
Snowflake's hybrid tables are the one real exception. Standard Snowflake tables keep both primary and foreign key constraints purely informational. Hybrid tables flip that: primary key constraints are required and enforced, and foreign key constraints are enforced right along with them. Any team building transactional SaaS features on top of hybrid tables is taking on real enforcement overhead, and the usual "declare it, test it downstream" advice does not apply there; picking hybrid tables over standard ones is itself a decision about where constraints get enforced.
One objection deserves a direct answer rather than a dismissal. A consultant auditing a Fortune 500 architecture found a flagship project with no primary or foreign key constraints declared anywhere, the implication being that if a project with that much visibility skips them, plenty of quieter projects are skipping them too. The lesson from that finding is not that enforcement was safe to skip. It is that declaring the constraint and running a transformation-layer assertion against it is a stricter discipline than skipping both, which is exactly the failure mode the consultant walked into. Declare the foreign key for the optimizer and the BI layer. Test it after load for the actual integrity guarantee. Neither one replaces the other.
How AI agents consuming warehouse schema depend on FK declarations being accurate
AI agents querying a warehouse through natural language read foreign key declarations as their map of how tables connect, and an agent with no accurate map cannot figure out which tables to join or how to join them. When FK declarations in the schema are inaccurate, an agent cannot infer which tables to join or how, and the SQL it generates degrades silently. It degrades quietly, producing a query that runs, returns a plausible-looking answer, and joins on the wrong column or skips a relationship the schema never told it about.
Snowflake Intelligence, launched in November 2024, is one concrete instance of where this is already live: an enterprise assistant built to let users query structured and unstructured organizational data in plain language, with agentic capabilities layered on top of governance and security controls. A system like that is only as reliable as the schema it is reading, and the schema is only as reliable as the foreign key declarations sitting inside it, which loops directly back to everything the earlier sections raised: whether the metadata is accurate, whether it survives the trip through JDBC or an SDK's model layer, and whether anything is actually testing it after the load runs. Get any one of those wrong and an agent will not throw an error. It will just answer confidently, and incorrectly, about a relationship that was never actually there.
Sources
- What Is a Foreign Key in SQL? Syntax, Rules, and Examples (2026) | DbSchema
- Referential integrity in a data warehouse | Data Warehouse Info
- Primary, Foreign, and Unique Keys - Microsoft Fabric | Microsoft Learn
- Foreign key referential integrity in the fact tables
- explicit Foreign Key constraints in DW - Ask TOM - Oracle
- community.fabric.microsoft.com
- Join Optimizations with BigQuery Primary and Foreign Keys | Google Cloud Blog
- Foreign Keys and Performance in a Microsoft Fabric Warehouse